Generative Engine Optimization
AI Crawlers, robots.txt and llms.txt: Which Bots to Allow and Why
Blocking 'AI bots' sounds simple until you realize some of them decide whether you appear in AI search at all. Here's a clear map of who crawls for what, and the robots.txt rules I actually use.
Sheikh Sadikur, SEO, AEO & GEO consultant
Published · 9 min read
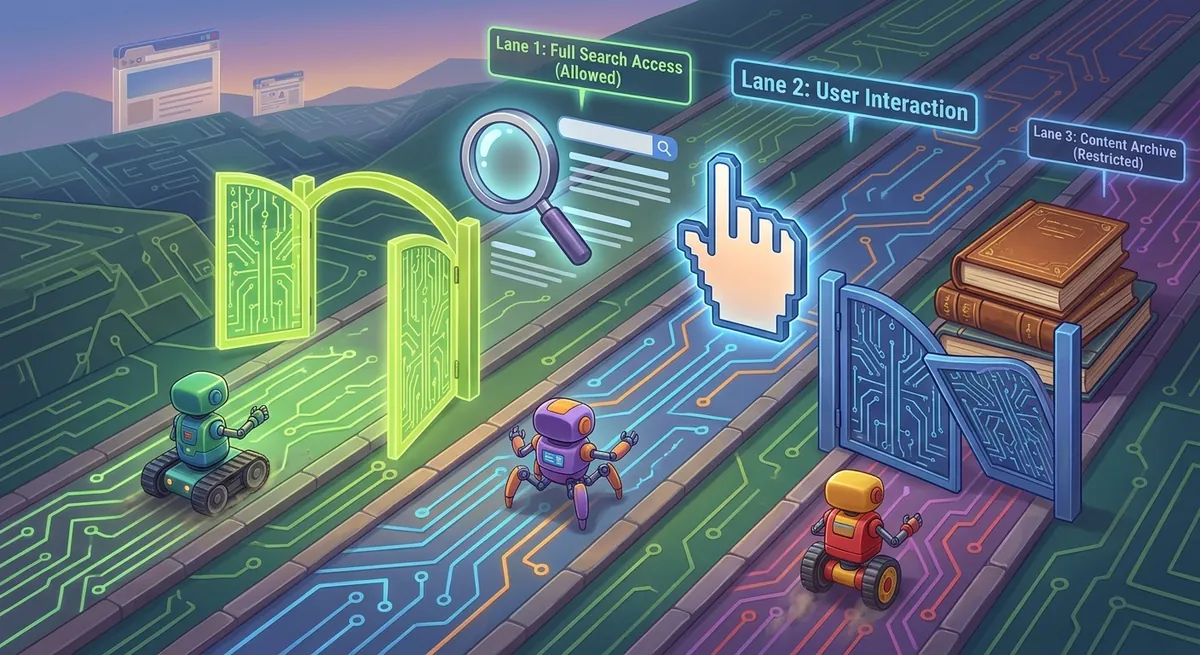
AI crawlers come in three kinds: search and retrieval crawlers that decide whether you can appear in AI answers, user-initiated fetchers that load a page when someone asks an assistant about it, and training crawlers that collect content to build future models. If you want to be cited in AI search, allow the search crawlers. Whether you allow training crawlers is a separate business decision. robots.txt lets you treat each one differently.
I've seen sites lose all AI visibility because someone pasted a "block all AI bots" snippet into robots.txt, and I've seen publishers give away content they meant to protect because they didn't know which bot did what. This guide is the map I use with clients.
The three kinds of AI crawler
| Type | What it does | Effect of blocking it |
|---|---|---|
| Search and retrieval | Builds the index an AI search product answers from | You stop appearing as a source in that product |
| User-initiated fetcher | Loads a page when a user asks the assistant to read it or a link is shared | Users can't get the assistant to read your page directly |
| Training | Collects content for future model training | Your content isn't used for training; search visibility is unaffected |
The mistake I see most is treating all three as one category.
The main crawlers, by company
These are the user agents the major companies document. Names change occasionally, so check each company's documentation before you rely on a rule.
| User agent | Purpose |
|---|---|
| Googlebot | Crawls for Google Search, including AI Overviews and AI Mode |
| Google-Extended | A robots.txt token, not a separate crawler. Controls whether content crawled by Google is used for Gemini apps and Vertex AI |
Two points matter. First, Google-Extended does not affect Google Search or AI Overviews, so blocking it won't remove you from AI Overviews. Second, if you want to stay out of AI Overviews, the controls are snippet directives such as nosnippet, which also affect normal search snippets.
OpenAI
| User agent | Purpose |
|---|---|
| OAI-SearchBot | Crawls for ChatGPT's search features |
| ChatGPT-User | Fetches pages on behalf of users during conversations |
| GPTBot | Crawls content that may be used for model training |
To appear in ChatGPT search, allow OAI-SearchBot. Blocking GPTBot only affects training. More on how ChatGPT chooses businesses is in how to get recommended by ChatGPT.
Anthropic
| User agent | Purpose |
|---|---|
| Claude-SearchBot | Crawls to improve search results in Claude |
| Claude-User | Fetches pages when a Claude user asks it to |
| ClaudeBot | Collects content that may be used for training |
Perplexity
| User agent | Purpose |
|---|---|
| PerplexityBot | Crawls to build Perplexity's search index |
| Perplexity-User | Fetches pages when a user asks a question |
Perplexity documents that its user-initiated fetcher generally doesn't follow robots.txt rules, since a person requested the page. If you need to block that traffic, you'd do it at the firewall level, not in robots.txt.
Microsoft
Bingbot crawls for Bing, which also powers Microsoft Copilot's web answers. Several other assistants have used Bing's index as one of their sources, so Bingbot access and a verified Bing Webmaster Tools account matter for AI visibility beyond Bing itself.
Apple
| User agent | Purpose |
|---|---|
| Applebot | Crawls for Siri, Spotlight and Safari suggestions |
| Applebot-Extended | A token that controls whether content is used to train Apple's models |
Others you'll see in logs
- CCBot (Common Crawl), whose open dataset is widely used in model training.
- Meta-ExternalAgent, Meta's crawler for AI training.
- Bytespider, ByteDance's crawler.
Deciding your policy
Ask two questions:
- Do I want to be cited and recommended by AI assistants? For almost every business that sells services or products, yes. Allow the search and retrieval crawlers.
- Am I comfortable with my content being used for training? For most service businesses, being included helps the model know about you. For publishers whose content is the product, blocking training crawlers may make sense.
Common policies:
| Business type | Search crawlers | Training crawlers |
|---|---|---|
| Service business, consultant, local business | Allow | Usually allow |
| E-commerce | Allow | Allow or block, depending on unique content |
| Publisher with paid or original content | Allow | Often block |
| Internal tools, staging sites | Block everything | Block everything |
robots.txt examples
Allow everything (my default for service businesses)
This is close to what I use on my own site:
User-agent: *
Allow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

Sitemap: https://example.com/sitemap.xml
The explicit groups aren't strictly necessary when User-agent: * allows everything, but they document intent and protect against someone later adding a broad block.
Allow AI search, block AI training
User-agent: *
Allow: /

User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: CCBot
Disallow: /

Sitemap: https://example.com/sitemap.xml
Search crawlers (Googlebot, Bingbot, OAI-SearchBot, PerplexityBot, Claude-SearchBot) fall under the * group and are allowed.
Protect a section, allow the rest
User-agent: *
Disallow: /members/
Disallow: /checkout/
Allow: /
How crawlers read groups
A crawler follows the most specific group that names it and ignores the others. If you create a User-agent: GPTBot group, GPTBot ignores the rules under User-agent: *. That's a common trap: people add a GPTBot group with one Disallow line and assume the general rules still apply to it.
Mistakes I find in audits
- Copy-pasted "block all AI" lists that include OAI-SearchBot and PerplexityBot, removing the site from AI search.
- CDN bot protection that challenges or blocks AI crawlers regardless of robots.txt. Check your CDN's bot settings and logs.
- Blocking CSS and JavaScript directories, so crawlers can't render pages. In one real estate project, 252 internal resources were blocked in robots.txt (case study).
- Using robots.txt to hide pages from search. A disallowed URL can still be indexed from links, without content. Use
noindexor remove the page instead. - Treating robots.txt as security. It's a public request, not access control. Anything private needs authentication.
Staging sites, duplicates and gated content
Three situations need extra care:
- Staging and development sites. These should be blocked from every crawler, AI or not, and ideally protected with a password. I've seen staging copies indexed and cited instead of the live site, which splits signals and confuses entity information.
- Old domains and mirrors. If you've moved domains, redirect the old one with 301s rather than leaving a duplicate copy online. An AI system that finds two versions of your content may cite the outdated one.
- Gated or paid content. If you show a summary to visitors and the full content to subscribers, make sure crawlers see the same thing users see. Serving crawlers different content from users is cloaking, and it can backfire in search.
What llms.txt is, and isn't
llms.txt is a proposed convention, introduced in 2024, for a Markdown file at the root of a site that summarizes the site and lists its most important pages with short descriptions. The idea is to give language-model tools a clean, curated entry point.
A minimal example:
# Example Studio

> Example Studio is a localization company in New York offering subtitling, dubbing and translation.

## Services

- [Subtitling](https://example.com/services/subtitling/): SDH and caption files for film and TV
- [Dubbing](https://example.com/services/dubbing/): studio and talent services in New York
What I tell clients honestly:
- Google has said it doesn't use llms.txt. Don't expect it to affect Google rankings or AI Overviews.
- No major AI search engine has confirmed it as a ranking or citation factor.
- It costs almost nothing. A well-written file takes less than an hour and can help tools and agents that do read it.
- Format matters if you add one. Lighthouse has added checks for llms.txt in its agentic browsing audits; a file without proper Markdown links can be flagged. When my own site's file used plain URLs instead of
[text](url)links, PageSpeed Insights reported that it didn't follow recommendations until I rewrote it.
So I add llms.txt as a tidy extra, never as a strategy, and I never let it distract from crawl access, content quality and authority.
Should you rate-limit AI crawlers?
Some site owners worry less about content use and more about load. Aggressive crawling can slow small servers, especially on shared hosting.
My approach:
- Don't block search crawlers to save bandwidth. The visibility you lose costs more than the server load you save.
- Use caching and a CDN. A static or well-cached site serves crawler requests cheaply. After I moved my own site from WordPress to static HTML on Hostinger with a CDN, crawler traffic stopped being a performance concern.
- Rate-limit at the CDN, not in robots.txt. The
Crawl-delaydirective isn't supported by Google and is inconsistently honored elsewhere. CDN rate rules give you real control. - Block abusive bots by behavior. If a crawler ignores robots.txt and hammers your server, block it at the firewall and verify its identity first, since fake user agents are common.
My ten-minute access check
When a new client asks why they're invisible in AI search, this is what I look at first, before anything else:
- Open
/robots.txtand read every group. Look for broad AI blocks and blocked CSS or JavaScript paths. - Fetch the homepage with a crawler user agent string and check the status code. A 403 or a CAPTCHA page is an immediate red flag.
- View the page source of a key service page and confirm the main content is in the HTML.
- Check Search Console's Pages report for excluded important URLs.
- Check Bing Webmaster Tools for crawl errors, or note that the site isn't verified there.
- Look for
noindex,nosnippetor restrictivemax-snippetin the HTML head.
Half the time, the answer to "why doesn't AI mention us" is somewhere in those six checks.
When to revisit your policy
Crawler names and company policies change. I review robots.txt rules for clients at least twice a year and whenever:
- A major AI company announces a new crawler or changes what an existing one does.
- The business changes its content strategy, for example by launching paid content.
- Logs show a new high-volume user agent.
- AI visibility drops suddenly for no content-related reason.
Keep a short comment at the top of robots.txt explaining the policy and the date it was set. It saves the next person from guessing.
How to check what's actually happening
Rules are only half the story. Verify behavior:
- Server or CDN logs. Filter by user agent to see which AI crawlers visit, how often and which status codes they get. A wave of 403 responses to OAI-SearchBot tells you something is blocking it.
- Verify the bot is real. Anyone can fake a user agent. Major companies publish IP ranges or support reverse DNS checks for their crawlers.
- Search Console's robots.txt report shows how Google reads your file and flags fetch errors.
- Bing Webmaster Tools shows Bingbot crawl activity and errors.
- Test in the assistant. Ask ChatGPT, Perplexity or Claude to read a specific URL. If it can't, check firewall rules for the user-initiated fetcher.
A technical SEO audit should include all of these checks. If you're investing in generative engine optimization, access is the first pillar for a reason.
A note for agencies managing many sites
If you manage robots.txt for several clients, keep a template per policy type (allow everything, allow search but block training, block everything for staging) and document which template each site uses. When a crawler changes or a new one appears, you can update every site consistently instead of editing files one by one from memory.
Frequently asked questions
Does blocking GPTBot remove my site from ChatGPT?
No. GPTBot collects content for model training. ChatGPT's search features use OAI-SearchBot, and user-requested page loads use ChatGPT-User. To stay visible in ChatGPT search, allow OAI-SearchBot even if you block GPTBot.
Does blocking Google-Extended remove me from AI Overviews?
No. Google-Extended controls whether your content is used for Gemini apps and Vertex AI. AI Overviews and AI Mode are part of Google Search and use Googlebot. To limit use in AI Overviews you'd need snippet controls like nosnippet, which also affect regular snippets.
Should a small business block AI crawlers?
Usually not. For most service businesses, being found and recommended by AI assistants is valuable, and being known to models helps that. Allow the search crawlers at minimum. Block training crawlers only if your content itself is what you sell.
Is llms.txt required for AI search?
No. It's an optional, emerging convention. Google has said it doesn't use it and no major AI search engine has confirmed it affects citations. It's fine to add one because it's cheap, but crawler access, clear content and authority matter far more.
Can robots.txt keep my content private?
No. robots.txt is a public, voluntary request that well-behaved crawlers follow. It doesn't stop people or badly behaved bots, and disallowed URLs can still appear in search from links. Use authentication for private content and noindex for pages that shouldn't be in search.